ブログ — ガイドと開発ノート
Jev を使った開発に関する製品アップデート、開発ノート、実践ガイド。型付きの質問と、コードで分岐できる構造化された回答について解説します。
最新の記事
Jev のユースケース:System One モデルが下せる 12 の判断
Jev に何ができるのか。チケットのトリアージからツール呼び出しのガードまで、エージェントやパイプラインで Jev が下す 12 の判断を、質問セットと無料のツールページ付きで紹介します。
 JevStation
Jev Benchmarks: Every Independent Test So Far
Is Jev accurate? Every independent Jev test to date, from an AI-control pilot to GLiNER and routing tests, with sample sizes, caveats and vendor claims apart.
JevStation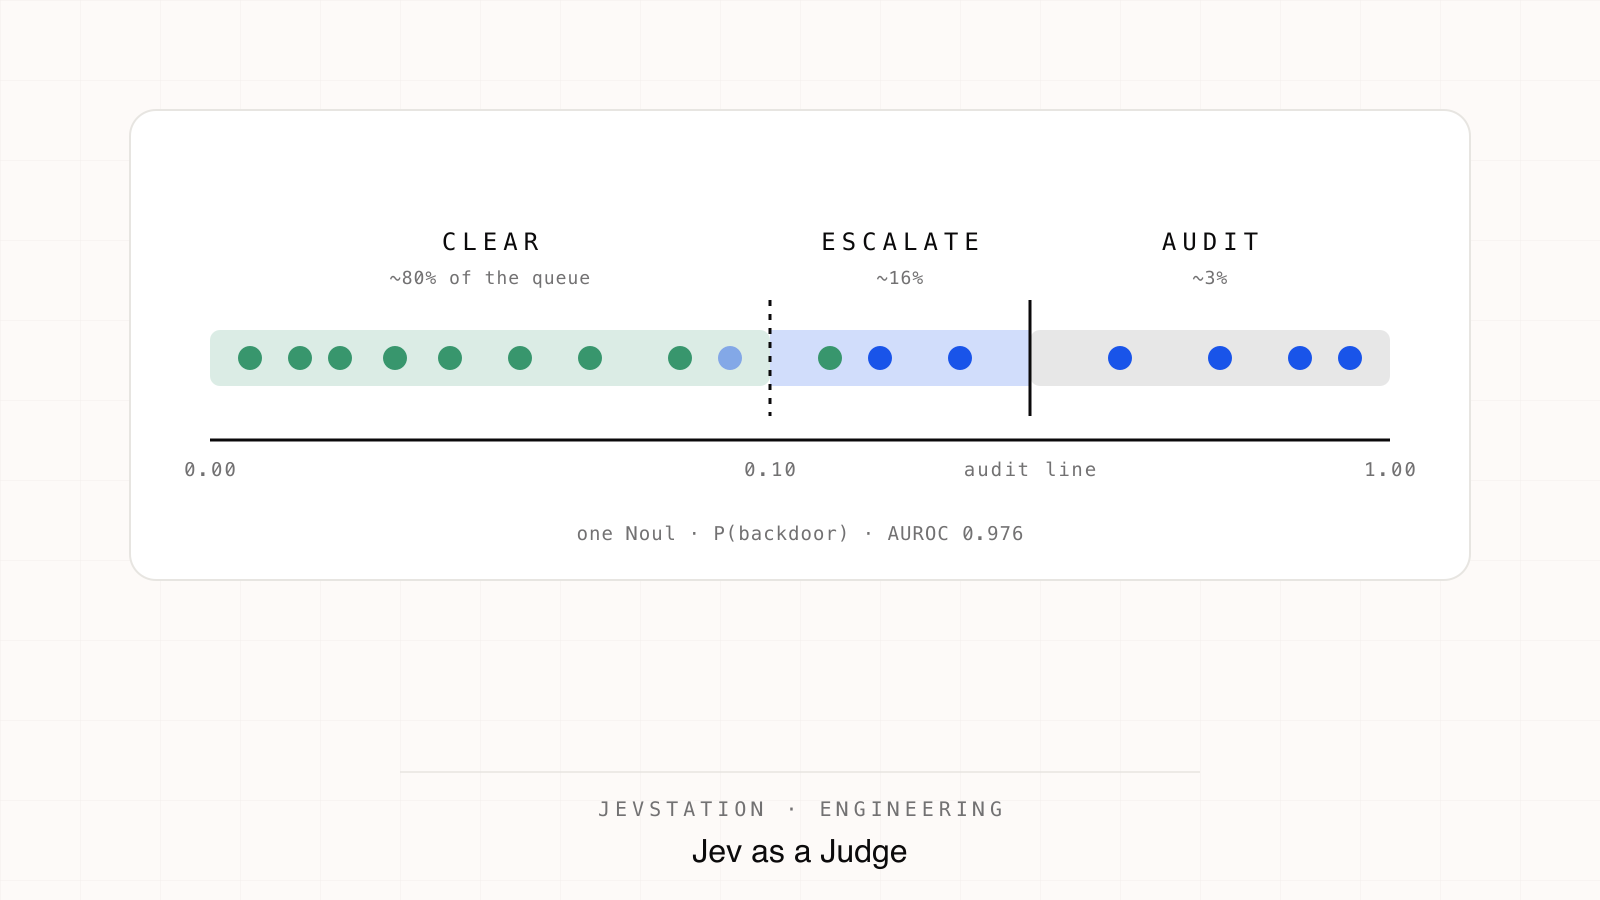
Jev as a Judge: What One Yes/No Question Catches
Can a text-free model judge LLM output? One Jev question ranks backdoored code at AUROC 0.976 for ~$0.04 per 1,000 checks. Where it holds, where it breaks.
JevStation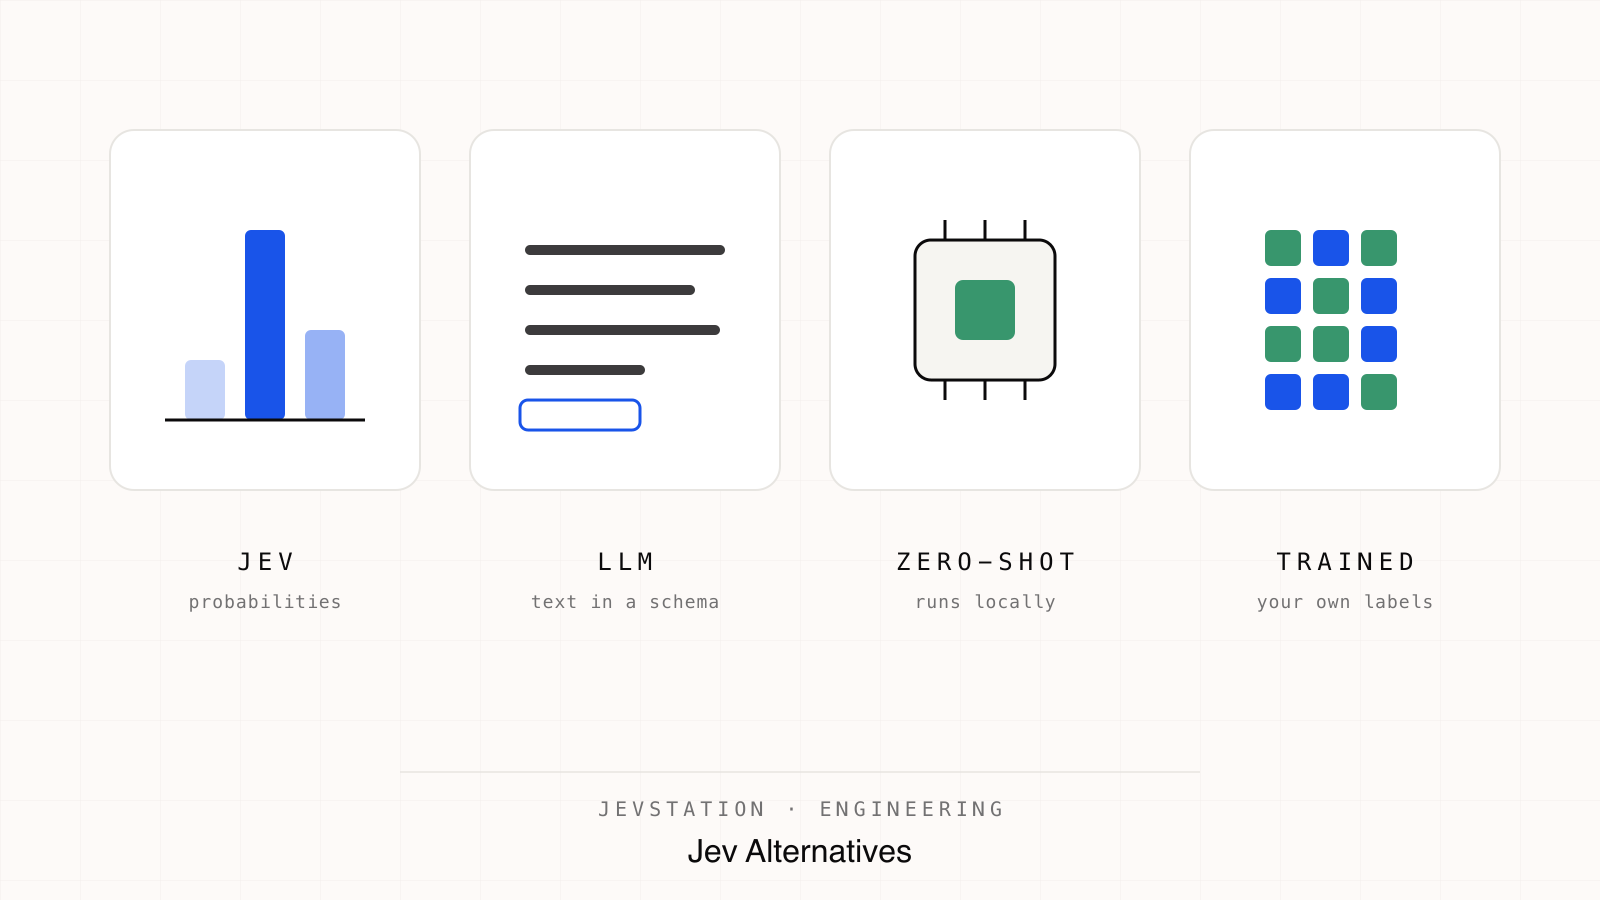
Jev Alternatives: LLMs, GLiNER, Custom Classifiers
Structured-output LLMs, zero-shot classifiers like GLiNER and self-trained models also return typed decisions. Where each beats Jev, with measured numbers.
JevStation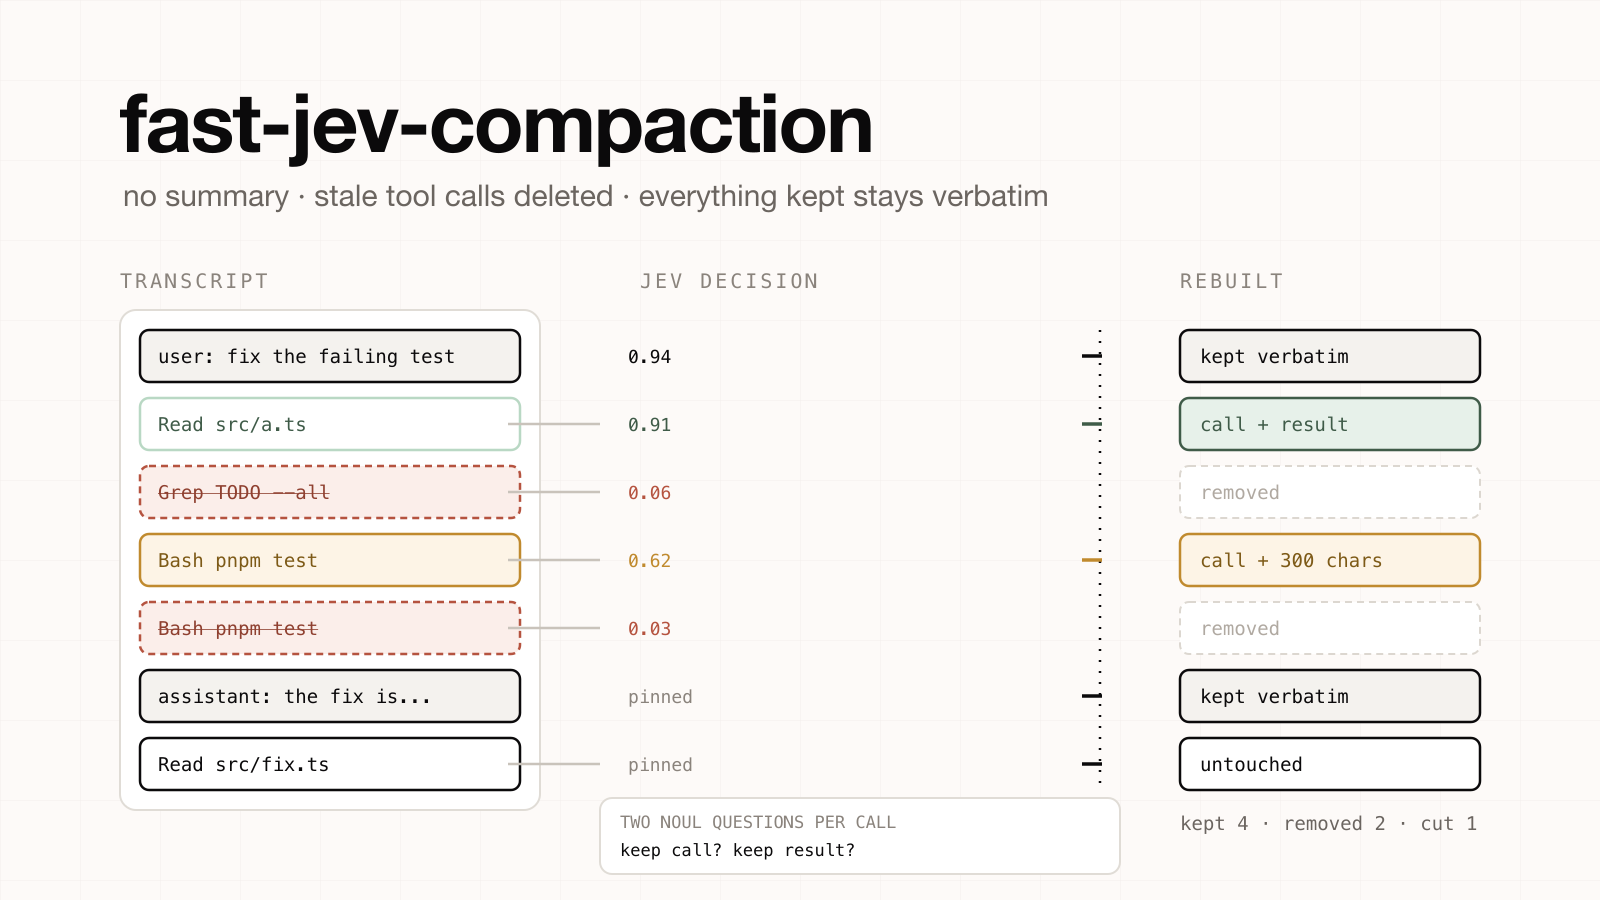
fast-jev-compaction: Compaction Without the Summary
A Claude Code plugin that replaces the compaction summary with Jev decisions: each tool call is scored, stale ones dropped, and everything kept stays verbatim.
JevStation
System One モデルとは何か、そして何ではないのか
System One モデルは生成テキストではなく、型付きの判断とキャリブレーションされた確率を返します。その意味、RLCD と RLHF の違い、そして独立した検証がまだ乏しい点を解説します。
JevStation
What One Jev Evaluation Costs, Measured
We made 11 real Jev calls across every state size and question count, fitted the token model and measured the cost: $0.000012 to $0.000377 per evaluation.
JevStation
Building a Harness with Jev
An agent loop is only as fast as its slowest decision. Where Jev, the System One model from TypeSafe, fits: model routing, action gating, escalation.
JevStation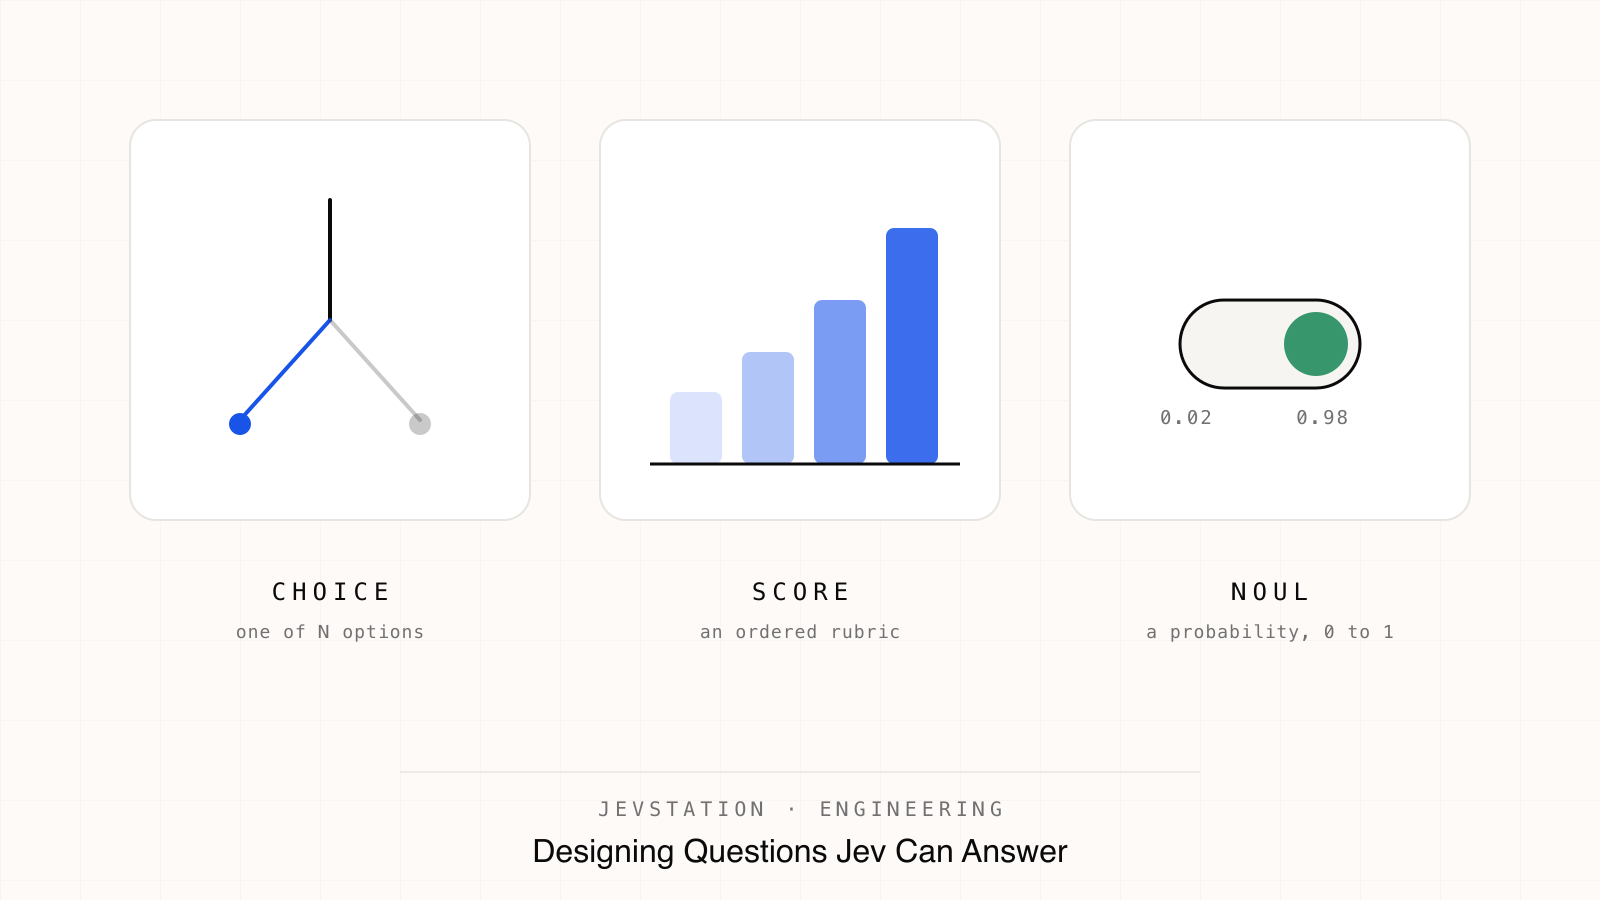
Jev が答えられる質問の設計:Choice、Score、Noul
Jev の 3 つの質問タイプ Choice、Score、Noul が、コードで分岐できる内容を決めます。それぞれの戻り値と制限、アトミックな質問の書き方、評価基準の磨き方、信頼度によるエージェントの行動制御を解説します。
JevStation