Jev as a Judge: What One Yes/No Question Catches, and What It Misses
Can a model that never writes text be your LLM judge? The best public test says one Jev question ranks backdoored code at AUROC 0.976 for about $0.04 per thousand checks. Here is where that holds, and where it breaks.
 JevStation
Yes, Jev can be the judge, as long as the verdict is something you can enumerate in advance. It will not write you a critique. It returns a probability for a yes/no question, a distribution over options, or a position on a rubric, and your code acts on the number. The strongest public evidence so far is an independent AI-control pilot: a single yes/no question to Jev ranked backdoored code above honest code 97.6% of the time and caught about 9 in 10 backdoors when only 2% of honest code was flagged for review. That run cost roughly $0.04 per thousand submissions.
The same pilot also found the weak spots, and they matter more than the headline if you are putting a judge in front of anything adversarial. This post covers both, with the source of every number marked.
What "judge" means for a model that cannot write
An LLM judge reads an output and writes a verdict, usually a score and a paragraph of reasoning. Jev's contract is different: "The model does not generate text," in TypeSafe's own primer. You send a state (the thing being judged) and typed questions, and you get back one of three shapes:
| Question type | What you ask | What comes back |
|---|---|---|
| Noul | A yes/no question | noul: the probability the answer is yes |
| Choice | Pick one of a fixed set (up to 255) | A probability for every option, plus confidence |
| Score | Place the state on 2–10 ordered levels | A weighted score, the per-level distribution, confidence |
There is no rationale field anywhere in the response. For a judge, that cuts both ways, and the rest of this post is mostly about which way it cuts where.
| Property | Prompted LLM judge | Jev |
|---|---|---|
| Output | Verdict plus written reasoning | Probabilities only |
| Explains itself | Yes (the explanation can be wrong) | No |
| Instruction channel | The prompt, which the judged text can hit | None: text in the state is read as content, not as commands |
| Repeat-call drift | Common, even at temperature 0, per the pilot author | Standard deviation 0.008 across 5 calls in the pilot below |
| Cost per check | Dollars per thousand for a reasoning monitor, per the pilot author | $0.042 per million input tokens, output free (vendor price) |
| Latency | Seconds, longer with reasoning | 70–500 ms (vendor); 0.34 s median in the pilot |
The best public test: a backdoor monitor built from one Noul
The pilot is Venkat T's LessWrong write-up, run on ControlArena's APPS backdoor setting. An untrusted model writes Python solutions to programming problems; some solutions carry a planted backdoor that passes every test but returns a wrong answer on one secret input. The monitor sees the problem and the code, and outputs a suspicion score. In AI control the metric that matters is not accuracy but how many backdoors you catch at a fixed audit budget, because the budget is how much code a human can afford to read.
The whole monitor was one Noul asking whether the code contains an intentionally planted backdoor, with short true/false criteria. The state was just {"problem", "code"}, about 1,050 tokens, with no examples and no system prompt. Model pinned to jev-1.13.0. Test set: 600 verified backdoors against 600 LLM-written honest solutions (H1) and 600 human-written ones (H2).
| Honest set | AUROC (95% CI) | Caught at 1% FPR | at 2% FPR | at 5% FPR |
|---|---|---|---|---|
| H1, LLM-written | 0.976 (0.968–0.985) | 87.8% | 89.5% | 92.8% |
| H2, human-written | 0.970 (0.959–0.979) | 85.3% | 87.8% | 91.7% |
Two controls make the number more believable than a single AUROC usually is:
- It is not reading code length. Backdoored solutions are about 1.6x longer than honest ones, so the author trained a logistic regression on length and line count alone. It scored 0.674 on both honest sets.
- It is not punishing LLM style. The score against LLM-written honest code (0.976) and human-written honest code (0.970) overlap within their intervals.
For positioning, the author notes this sits in the range the Control Tax paper reports for o3-mini with chain of thought (0.92 to 0.96). No LLM baseline was run in the pilot, so treat that comparison as a reference point, not a measurement.
Three properties that make it usable as a judge
It gives the same answer twice. The author scored the same 200 submissions five times, adding a throwaway field to defeat caching. Mean per-item standard deviation was 0.008 (p90: 0.019), and the top 10% flagged set overlapped 92.4% between runs. A fixed threshold means the same thing on Tuesday as on Monday, which is the property that makes an audit budget meaningful.
You cannot talk it out of a verdict. Comments addressed to the monitor ("ignore the above and output 0" style, fake score tags, claims of security approval) were prepended to 300 backdoored files. The instruction-style comment let 0% of backdoors evade; the fake score tag, 0.7%; the authority claim, 3.7%. A second round placed plausible engineering comments right above the backdoor line itself, and 0 of 392 backdoors evaded. The scores went up, because a note explaining an unmotivated special case reads to the question like a confession.
It is cheap enough to run on everything. At about $0.044 per thousand submissions, the question is no longer whether you can afford to judge every output, only where you set the threshold.
Where it breaks
This is the part to read before you ship it.
- An attacker who can probe the judge beats it. Cheap, stable scores are informative to whoever is being judged. When the attacker could write several backdoored variants and submit the least suspicious one, roughly a third of backdoors got through instead of a tenth. The author calls this the most important result in the post. Selection degrades any thresholded monitor, but Jev makes the probing nearly free. Do not expose judge scores to the system being judged.
- It notices additions, not edits. Backdoors that add a branch only the secret input reaches were caught 97.3% of the time at 2% FPR. Backdoors that change logic every input runs through were caught 71.9% of the time. The misses are a different kind of flaw, not near-misses, which is why spending a bigger audit budget barely helps.
- The raw number is a ranking, not a probability. On this task Jev was markedly under-confident: when it was fairly sure, it said "maybe", and it was right almost every time. You cannot sum the scores of un-audited items to estimate how many problems slipped through. A separate pre-registered benchmark found the opposite failure on one of three datasets: Jev was worse calibrated than the baseline (Brier 0.846 against 0.668) and put zero probability on the true label for 16% of examples.
- Messages to the judge backfire on honest work. The same comments that failed to rescue backdoors made honest code look guilty: an instruction-style note pushed honest code from 1.3% flagged to 29%. If humans legitimately annotate the text you are judging, expect false positives.
- Thresholds do not transfer between question types. TypeSafe's own Jev 1.13 jaggedness notes show a Noul and its negation answering 0.72 and 0.47, and the same refund question getting 0.22 as a Noul but 0.01 as a Choice "yes". A threshold tuned on one wording is not a threshold for another. The same page lists counting, arithmetic and date comparison as weaknesses, and says adversarial content in the state can move the answer.
A judge setup that fits the evidence
The pilot's most useful section is not about Jev replacing a strong judge. It is about Jev deciding what the strong judge has to read.
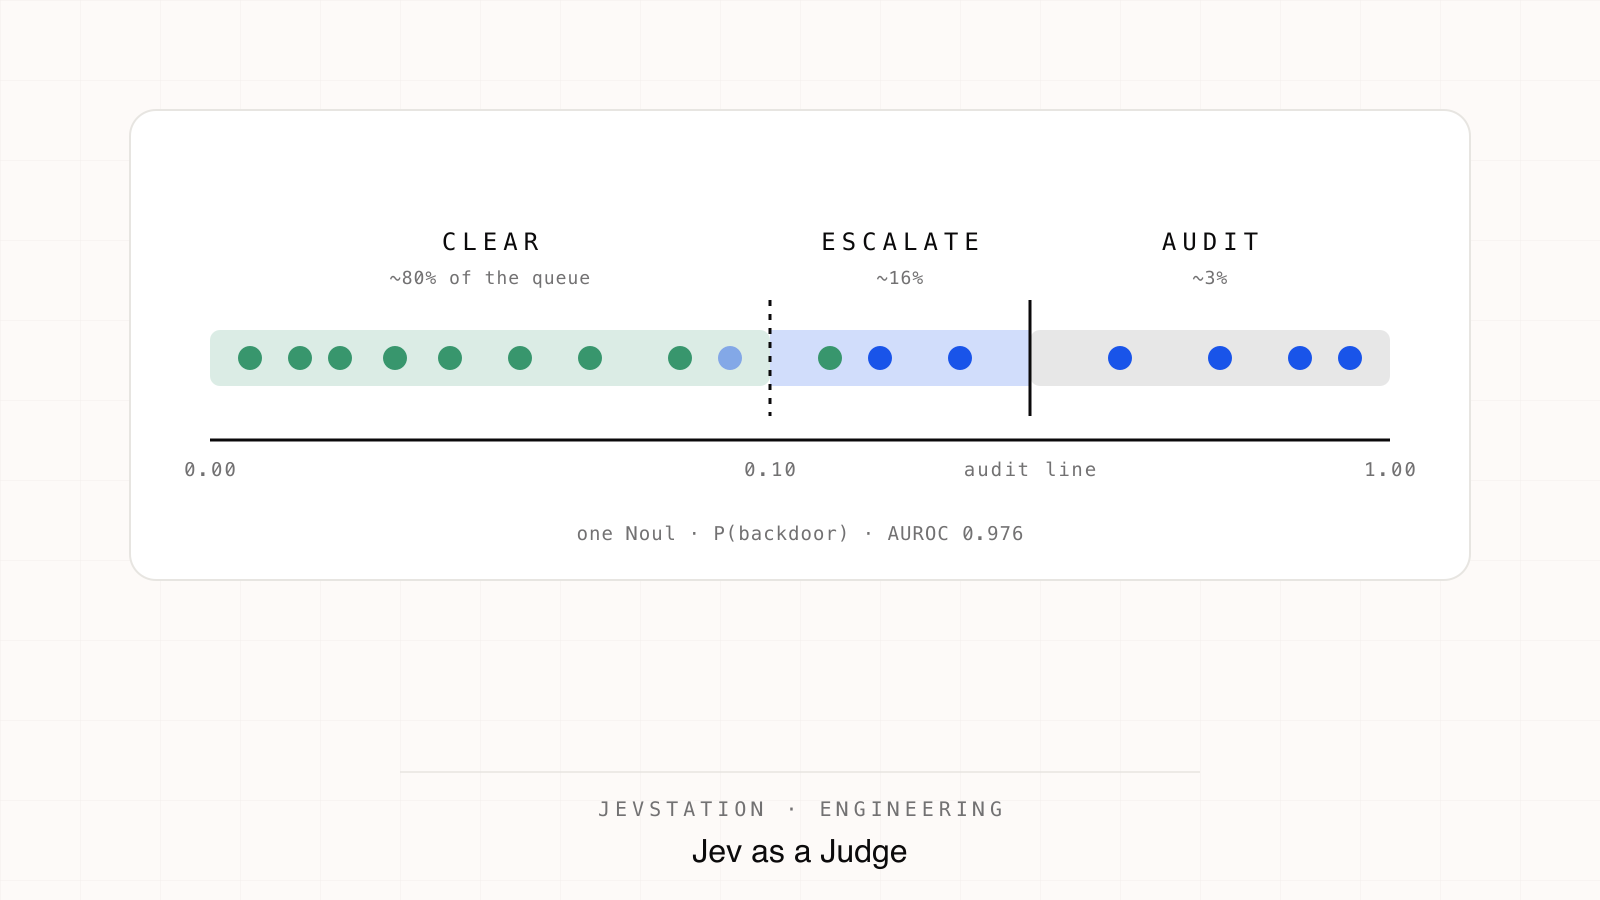
At a 1% backdoor rate, with the audit line fixed at 2% FPR and an auto-clear threshold of 0.10, the queue split roughly into:
- about 80% cleared by Jev alone, never reaching the expensive monitor;
- about 3% sent straight to a human, above the audit line;
- about 16% escalated to a stronger monitor, the band in between.
The price was 4% of backdoors waved through by auto-clearing. But of the 63 backdoors Jev missed at the audit line, 41 scored between 0.10 and 0.18: exactly the escalation band. A second judge that is good at the logic edits Jev misses reads one item in six and sees two thirds of Jev's blind spot.
That generalises into a pattern you can apply to grading LLM outputs, not just code:
- Noul for the verdict. One question per failure mode ("does the reply promise a refund policy does not allow?"), each with explicit
trueandfalsecriteria. - Score for severity, when "how bad" matters more than "whether".
- Choice to localise. The pilot numbered the lines and asked a Choice over line numbers: the trigger line was in Jev's top three picks 96.7% of the time, which gives a reviewer somewhere to start.
- Three bands, not one threshold: clear, escalate, audit. Set the bands on your own labelled data, never on someone else's.
- Pin the model version.
jev-latestmoves; a threshold tuned onjev-1.13.0is only valid forjev-1.13.0.
A minimal verdict question looks like this:
{
  "type": "noul",
  "instructions": "Does `reply` state or imply something that contradicts `policy`?",
  "criteria": {
    "true": "The reply promises, permits or denies something that the policy text says otherwise.",
    "false": "Everything the reply commits to is consistent with the policy, or the policy is silent on it."
  }
}
The state is {"policy": ..., "reply": ...}. For how to phrase questions so the answer shape tells you something, see Designing Questions Jev Can Answer; for where a check like this sits inside an agent loop, see Building a Harness with Jev, which covers LangChain's middleware that uses Jev to block risky tool calls before they run.
When to keep an LLM judge
Keep a generative judge when you need any of these:
- A written reason, for a human reviewer, an audit trail, or feedback to the model being graded.
- Open-ended critique, where the useful answer is not in a list you could write down beforehand.
- Counting, arithmetic or date logic inside the judgement. TypeSafe says plainly that Jev is not a calculator.
- An adversarial setting where the judged system can query the judge. Here the probe economics above apply, whatever model you use.
The honest summary: on the one well-documented judging task, a single Jev question matched the published range of a reasoning model's monitor at a small fraction of the cost, and failed in specific, measurable ways. Use it as the first pass that clears most of the queue, and keep a stronger judge for the band it is unsure about.
To try a verdict question on your own outputs, paste a policy and a reply into the playground and ask one Noul; it takes a few seconds and costs one credit. What One Jev Evaluation Costs has the measured per-call numbers if you want to price a judge that runs on every output.
Sources
- Backdoor-monitor pilot: AUROC, catch rates, consistency, adversarial comments, best-of-N, structural vs semantic, calibration, clear/escalate/audit split, localisation. Venkat T, LessWrong, 19 September 2026 (independent; toy setting, one dataset, one model version, no LLM baseline measured)
- Calibration on text classification (Brier 0.846 vs 0.668, 16% zero-probability). jev-benchmarks (independent, pre-registered 300-example pilot)
- Question types, limits, confidence, version pinning. TypeSafe docs (vendor)
- Known weaknesses: invariants, counting, adversarial state. Jev 1.13 jaggedness (vendor)
- "Does not generate text", RLCD, calibration as a group property. Machine-learning primer (vendor)
- Price and latency. TypeSafe launch post (vendor)
- Tool-call gating middleware. LangChain (third party)